Four acronyms, two actual ideas
Since AI answers became a normal part of search, the industry has produced four new acronyms. They are used interchangeably in most articles, which is unhelpful, because two of them describe genuinely different work.
| Term |
Stands for |
What it actually covers |
| AEO |
Answer Engine Optimization |
Structuring content so a machine can extract a clean, attributable answer from it |
| GEO |
Generative Engine Optimization |
Being named and recommended inside AI-generated answers |
| LLMO |
Large Language Model Optimization |
Broadly a synonym for GEO; occasionally used for training-data influence |
| GXO |
Generative Experience Optimization |
Preparing for autonomous agents that transact, not just answer |
Strip the marketing and you are left with two ideas that matter today and one that matters soon.
AEO is an input. It is work you do to your own pages — structure, markup, phrasing, entity clarity. You control it completely, and you can audit it.
GEO is an outcome. It is whether models actually name you. You influence it but do not control it, and the only way to know how you are doing is to measure it directly.
LLMO is, in nearly all practical usage, GEO with a different label. GXO is real and coming, but if you have not solved the first two, optimising for agentic commerce is premature.
The distinction that matters: AEO is what you do. GEO is what happens. Treating them as one thing is why so many teams report doing “AI SEO” without being able to say whether it worked.
AEO: five things a model needs from a page
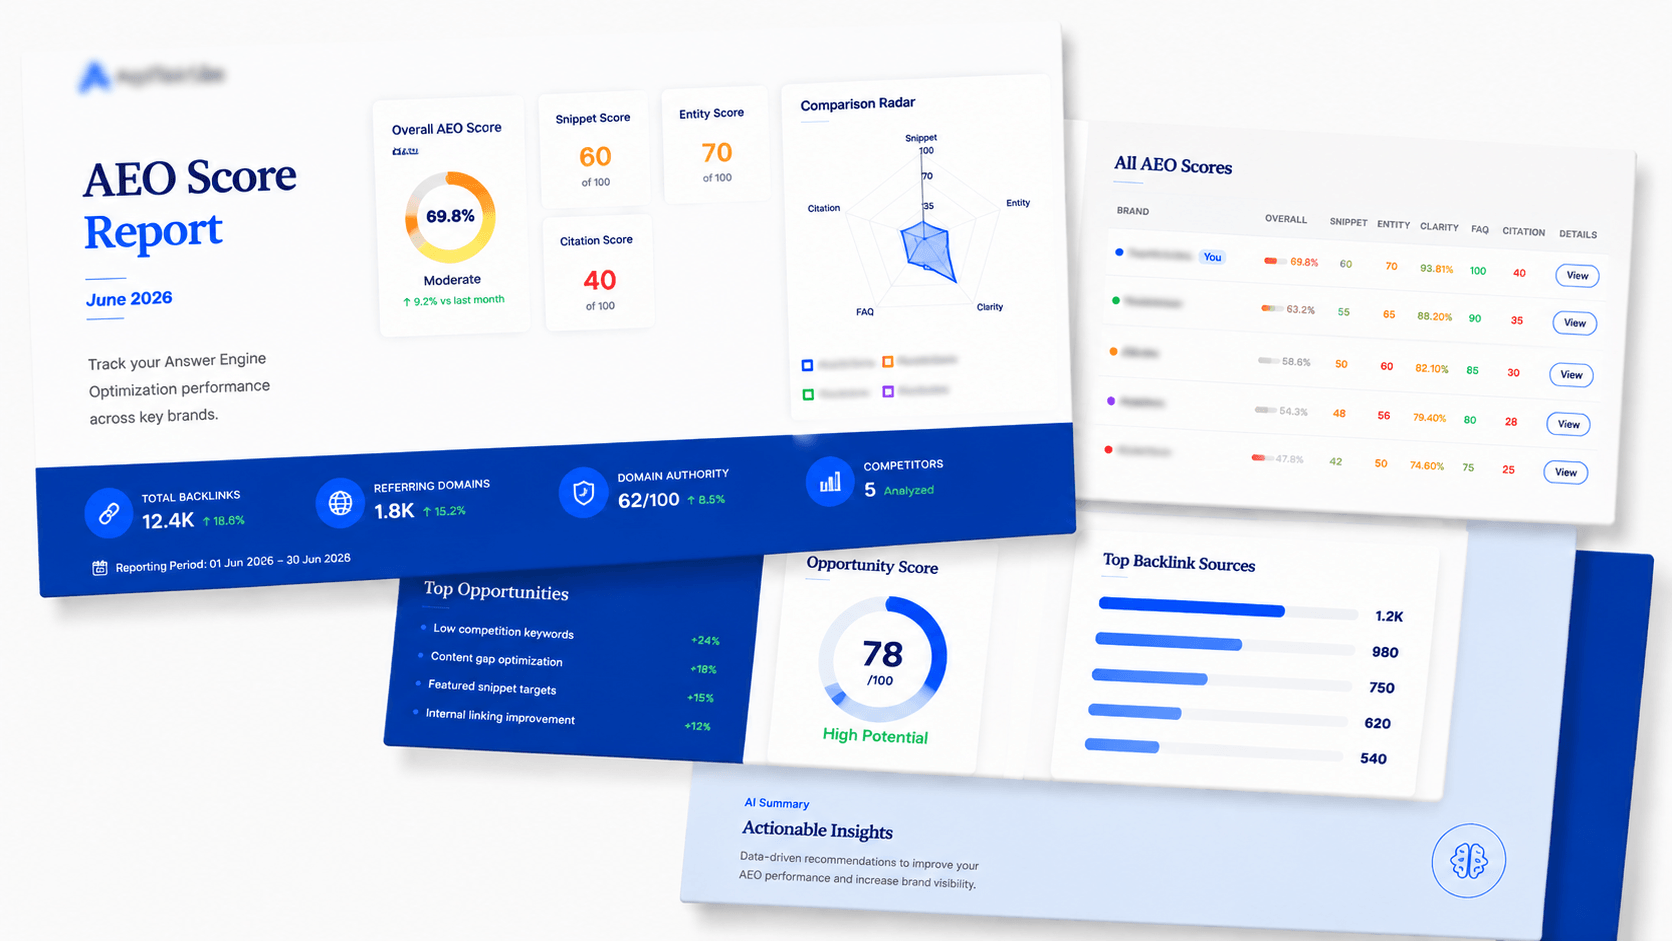
When an assistant reaches for a source, it needs a passage it can lift cleanly, an entity it can identify confidently, and a claim it can attribute. Those requirements decompose into five measurable dimensions.
Snippet readiness
Is there a direct, self-contained answer near the top of the relevant section? A page that opens a section with a 40–60 word answer is substantially more quotable than one that reaches the same point in paragraph six. This is the single highest-leverage change most sites can make, and it costs nothing but editing.
Entity clarity
Can the model confidently identify who and what the page is about? Explicit Organization, Person, Product and LocalBusiness markup removes ambiguity. Ambiguity makes a model hedge, and a hedging model tends to cite someone else.
Answer clarity
Is the claim unambiguous enough to quote without qualification? Content hedged into meaninglessness — “results may vary depending on many factors” — is safe for legal and useless for extraction.
FAQ presence
Are the obvious follow-up questions answered on the page? This is the dimension most sites score zero on, and it is also the cheapest to fix. Draft the questions, answer them honestly, publish with FAQPage markup.
Citation probability
Author attribution, publication and update dates, cited sources, consistent business details. These are trust signals, and trust has become the primary filter for AI inclusion rather than a tiebreaker.
GEO: measuring the outcome
You can do all five AEO things well and still not be named, because a model’s choice depends on the whole corpus it has to choose from — not just on your page. That is why GEO has to be measured rather than assumed.
Measurement means a fixed prompt set, run on a schedule, across every engine your buyers plausibly use. For each response, record four things:
- Were you named? Yes or no, per engine, per date.
- Who was named instead? The competitor list is often more actionable than your own appearance rate.
- What was the sentiment? Being mentioned as a cautionary example is not a win, and a visibility chart that ignores sentiment will happily report it as one.
- Which sources were cited? This is the field that turns measurement into a content plan.
The most common GEO mistake: Optimising for the engine you personally use. Visibility distributions differ sharply across ChatGPT, Gemini, Claude, Perplexity and Google’s AI surfaces. A strategy tuned on one of them will produce confident, wrong conclusions about the others.
Which one deserves budget first
For nearly every team, the order is the same, and it is not the order the acronyms are usually presented in.
- Measure GEO first, cheaply. Before changing anything, find out where you actually stand. A month of manual prompt checks costs a few hours and prevents a quarter of misdirected work. You cannot prioritise fixes without a baseline.
- Then fix AEO on your highest-impression pages. Not the whole site. Pull the twenty pages with the most Search Console impressions and work through the five dimensions on those. FAQ blocks and opening-paragraph answers first, because they are fast and they move the score.
- Then extend structured data site-wide. Slower, more technical, and the benefit compounds rather than spikes.
- Then re-measure. Same prompt set, same engines. This is the step teams skip, and skipping it means never learning which of the changes actually mattered.
GXO — optimising for agents that act rather than answer — is worth reading about and not yet worth staffing, unless you sell something an agent could plausibly buy without a human present.
A reasonable first quarter: Weeks 1–4: baseline 20 prompts across 3+ engines. Weeks 5–8: AEO fixes on the top 20 pages by impressions. Weeks 9–12: schema rollout and re-measurement. That is a full cycle, it produces a defensible before-and-after, and none of it requires new headcount.
Does classic SEO still matter?
Yes, and the framing of the question is the problem.
Every one of the AEO dimensions is also a classic SEO improvement. Clear structure, unambiguous answers, valid markup, real author attribution and genuine topical depth were good practice before assistants existed. What has changed is that the penalty for skipping them has gone up, and a second measurable surface now exists where the benefit shows.
The teams struggling right now are mostly not the ones with weak AEO. They are the ones who spent years producing content that ranked without being useful — thin comparison pages, keyword-shaped articles with no real position. That content ranked because links and volume could carry it. It does not get cited, because there is nothing in it worth quoting.
The fastest route to being cited by an AI is to write something a knowledgeable human would want to quote. Everything else is formatting.
Which is an unsatisfying conclusion for anyone hoping the new acronyms describe a shortcut. They do not. They describe a more legible standard for the same underlying quality — and, usefully, a way to measure whether you are meeting it.
Sources